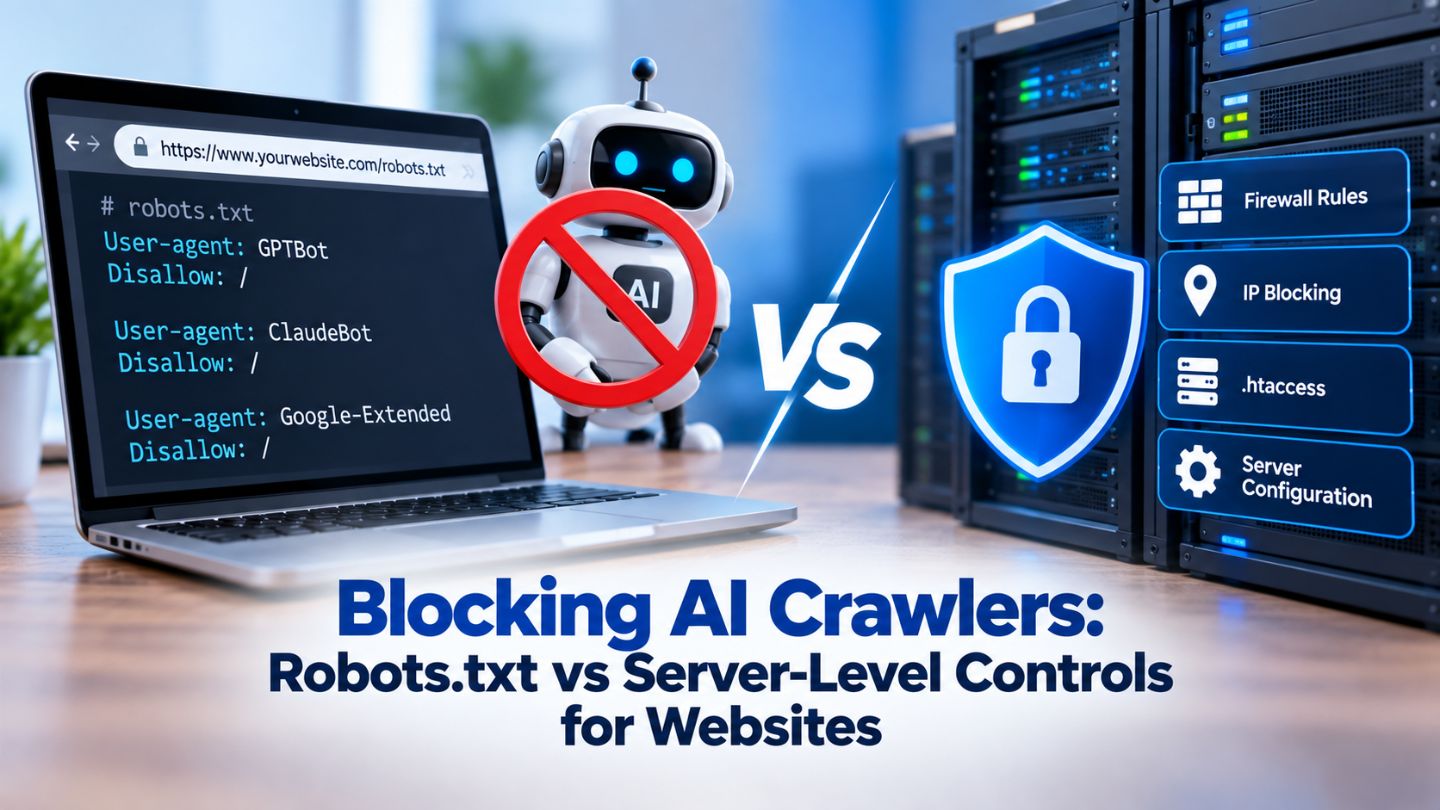
Deciding whether to let AI crawlers access your site has become a real question rather than a technical afterthought, and the two main ways of enforcing that decision, robots.txt and server-level controls, work very differently and fail very differently. One is a polite request; the other is an actual barrier. This blog covers how each approach works, what each can and cannot do, and how to think about which content you actually want to block versus allow in the first place.
Key Takeaways
- txt requests access behaviour; server controls enforce it.
- Not every AI crawler respects robots.txt directives.
- Blocking crawlers can also remove you from AI-driven visibility.
- Server-level blocking is stronger but easier to misconfigure.
- The decision is strategic, not just technical.
How Robots.txt Actually Works
Robots.txt is a file that tells crawlers which parts of your site they are asked not to access. The key word is asked. It is a convention that well-behaved crawlers follow voluntarily, not a lock. A crawler that chooses to ignore it faces no technical obstacle, because nothing about robots.txt physically prevents access.
For the major, reputable crawlers, this is usually enough, since they honour the directives as a matter of policy. The gap appears with crawlers that either do not check robots.txt or choose to disregard it, and those are exactly the ones you might most want to block. Understanding whether robots.txt is an SEO risk or a strategic optimization tool matters here, because misusing it can cause problems well beyond AI crawlers.
How Server-Level Controls Differ
Server-level blocking enforces the decision rather than requesting it. By identifying and refusing requests from specific crawlers at the server, you create an actual barrier that does not depend on the crawler's goodwill. A blocked request simply does not get served, regardless of whether the crawler would have respected a polite instruction.
This is stronger and correspondingly easier to get wrong. Blocking by user agent can be evaded by crawlers that disguise themselves, blocking by IP range requires keeping those ranges current, and an overly aggressive rule can accidentally block legitimate traffic or search engines you actually want. The power of the approach is exactly why it needs care.
Identify Before You Block
Check your server logs to see which crawlers are actually visiting before writing rules. Blocking crawlers that never visit accomplishes nothing, and it is easy to write a rule against the wrong user agent string.
Read More: Difference Between Crawling and Indexing in Search Engine Optimization (SEO)
What You Might Actually Want to Block
The blanket instinct to block all AI crawlers is worth questioning, because it is rarely the right call across an entire site. Some content you may genuinely want kept out of training data or AI answers; other content you may want cited as widely as possible, because being referenced in AI-generated responses is a visibility channel rather than a threat.
That argues for a selective approach rather than an all-or-nothing one. Proprietary material, gated content, and anything you consider a competitive asset are reasonable candidates for blocking. Your public, informational content that you want people to find is usually not, since blocking it removes you from exactly the surfaces where discovery is increasingly happening. Reviewing how LLM bots read websites helps make that distinction deliberately. It is also worth knowing what an LLMS.txt file does, since it signals intent rather than enforcing access.
The Visibility Trade-Off
Blocking AI crawlers is not a free action with no downside. As AI-driven search and assistants become a larger part of how people find businesses, being invisible to those systems means being absent from answers your competitors may appear in. The block that protects your content also removes it from a growing discovery surface.
This is the genuine tension at the heart of the decision. There is a real argument for protecting certain content and a real cost to protecting all of it, and the right balance depends on what your content is for. Content that exists to attract and inform customers usually benefits from being accessible; content that represents proprietary value may not. Treating it as a single yes-or-no decision misses that nuance entirely.
Read More: AI Search Traffic Explained: How ChatGPT, Gemini & Perplexity Discover Content
Common Configuration Mistakes
The errors here are consistent and avoidable. Blocking a crawler in robots.txt and assuming it is enforced, when robots.txt is only a request. Writing server rules against outdated user agent strings that no longer match anything. Accidentally blocking legitimate search crawlers alongside AI ones, which damages your traditional visibility for no benefit.
There is also the opposite error: believing you have blocked something when a misconfiguration left it open. Verifying that your controls actually do what you intended, by checking logs and testing, is the step most often skipped. A block you never confirmed is a decision you only think you made. The same care applies as with any technical SEO audits with free tools.
The Content-by-Content Approach
The most sensible way through this is to stop treating it as one decision and start treating it as a set of them, section by section. Your public informational content, the material you want people to find, usually benefits from being accessible to AI crawlers, because that accessibility is what lets it be surfaced. Your proprietary, gated, or competitively sensitive content is where blocking makes genuine sense.
This granular approach takes more thought than a blanket rule, and it produces a far better outcome. Rather than either exposing everything or hiding everything, you make a deliberate choice about each kind of content based on what it is for. That is more work upfront, and it avoids both failure modes: being invisible where you wanted visibility and being exposed where you wanted protection. For the content you do want reached, citation SEO explains what turns access into an actual mention.
Revisiting the Decision Over Time
Whatever you decide now is not permanent, and the landscape here is moving quickly enough that a decision made today may not fit in a year. The crawlers change, the way AI systems use content changes, and the balance between the visibility benefit and the protection concern shifts as AI-driven discovery becomes a larger or smaller part of how people find businesses.
This argues for treating your crawler policy as something to review periodically rather than set once and forget. A block that made sense when AI search was marginal may cost more as it grows, and an openness that felt risky may prove valuable. Building in a periodic reassessment keeps the decision matched to a reality that keeps changing rather than frozen to how things looked when you first configured it.
Verifying the Block Actually Works
Whatever approach you choose, the step most often skipped is confirming it actually does what you intended. A robots.txt rule you assume is enforced, a server block written against an outdated identifier, or a configuration that quietly failed all leave you believing you made a decision you did not actually implement. The gap between intended and actual is where most crawler-control mistakes live.
Checking your logs to see what is actually being served, and testing that your rules behave as expected, is what turns an assumed block into a real one. This verification is unglamorous, and it is the difference between a policy you think you have and one you actually have, which matters most for exactly the content you most wanted to protect or expose.
Making a Deliberate Decision
Blocking AI crawlers comes down to choosing between a polite request and an enforced barrier, and then deciding what actually deserves blocking in the first place. Robots.txt is simple and voluntary; server-level controls are stronger and riskier. Neither should be applied as a blanket rule, because the same block that protects proprietary content can erase you from the AI-driven visibility your public content depends on. Decide by what each piece of content is for, configure carefully, and verify that your controls do what you think they do.
At The Ocean Marketing, we help businesses make these SEO decisions deliberately rather than reactively. Whether you need help deciding what to block, configuring controls that actually work, or a free SEO audit to see where your site currently stands, our team can help. Contact us and let's work out the right approach for your content.